
Introduction
In this article, we will see how to set up Scala in IntelliJ IDEA and we will create a Spark application using the Scala language and run it with our local data. I am using Indian Pincode data to analyze the state-by-state post office details.
Scala is a very powerful object-oriented and functional programming language. Scala's static types help avoid bugs in complex applications, and its JVM (Java Virtual Machine) lets you build high-performance systems with easy access to huge ecosystems of libraries.
Scala source code is intended to be compiled to Java bytecode so that the resulting executable code runs on a Java virtual machine (JVM).
Scala provides language interoperability with Java, so that libraries written in both languages may be referenced directly in Scala or Java.
Please refer to the official Scala documentation for more details.
As Scala runs in JVM, it needs a Java Runtime/Java Development Kit.
Step 1 - Install Java Development Kit (JDK version 8)
Please note that Scala’s latest version (2.11/2.12) is not fully compatible with higher versions of Java. We must choose the Java 8 version to avoid issues.
Please download JDK version 8 from this URL and install it to your windows machine.
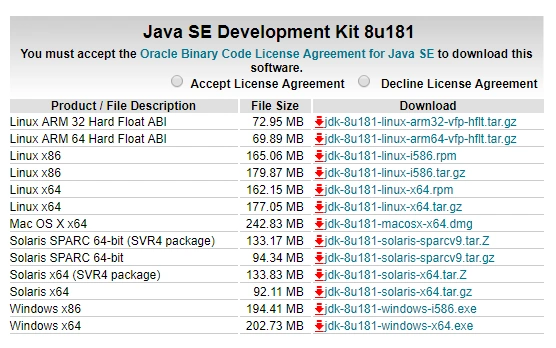
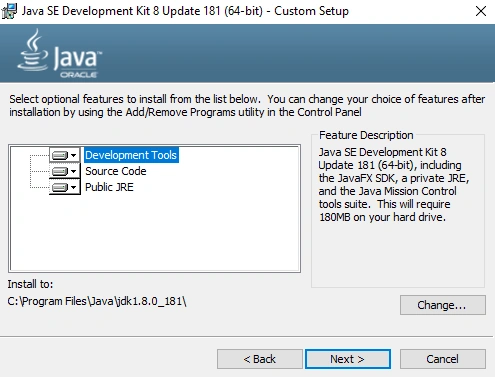
Please accept the license agreement and install it. This will first install JDK to your system.
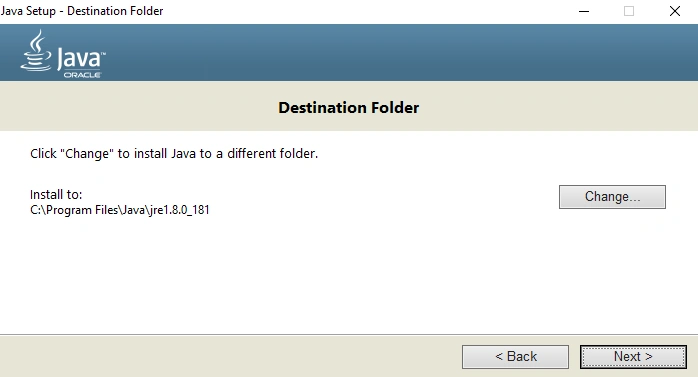
After installing the JDK it will install Java Runtime also (JRE)
Step 2 - Install IntelliJ IDEA with Scala and Azure Plugins
We have now successfully installed JDK and JRE in our system. Now we can install IntelliJ IDEA in our machine. This is a wonderful IDE suitable for Java and Scala development. It is a product of JetBrains company. Please download IntelliJ free community edition from this link
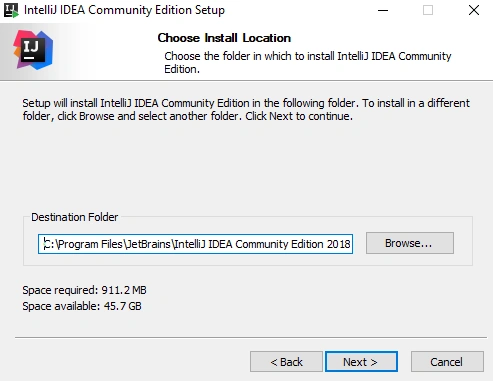
We can install the Scala plugin along with the IntelliJ installation. If you forgot to install it, please install this plugin separately.
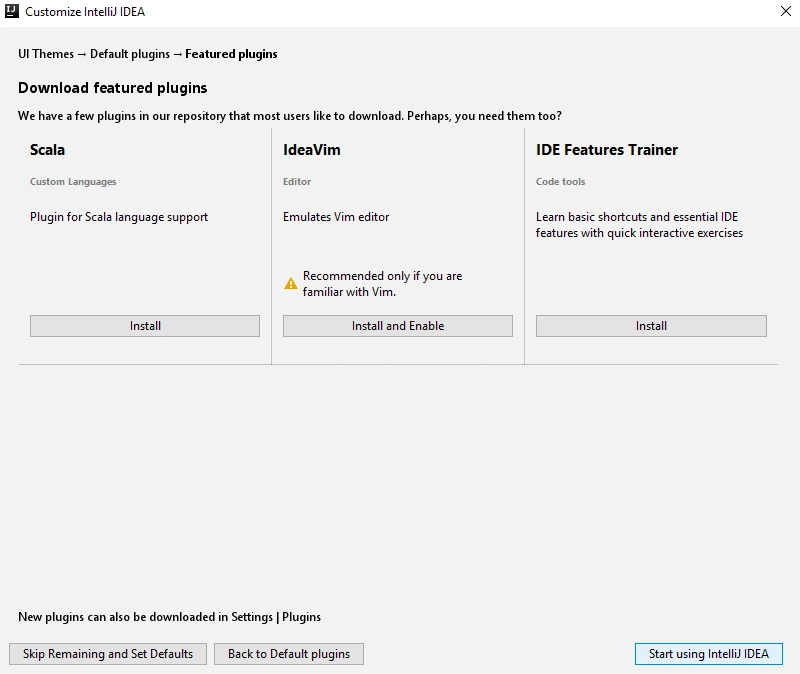 Our installation will take some time to finish and after installation, we can open the IntelliJ IDEA.
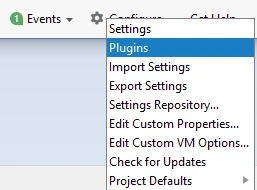
We are going to work with Spark and Scala along with Azure HDInsight. We need an Azure plugin too. Please click “Configure” and choose “Plugins” from the dropdown list.
We can search for Azure and will find an Azure Toolkit for IntelliJ. Please install this plugin to your IntelliJ.
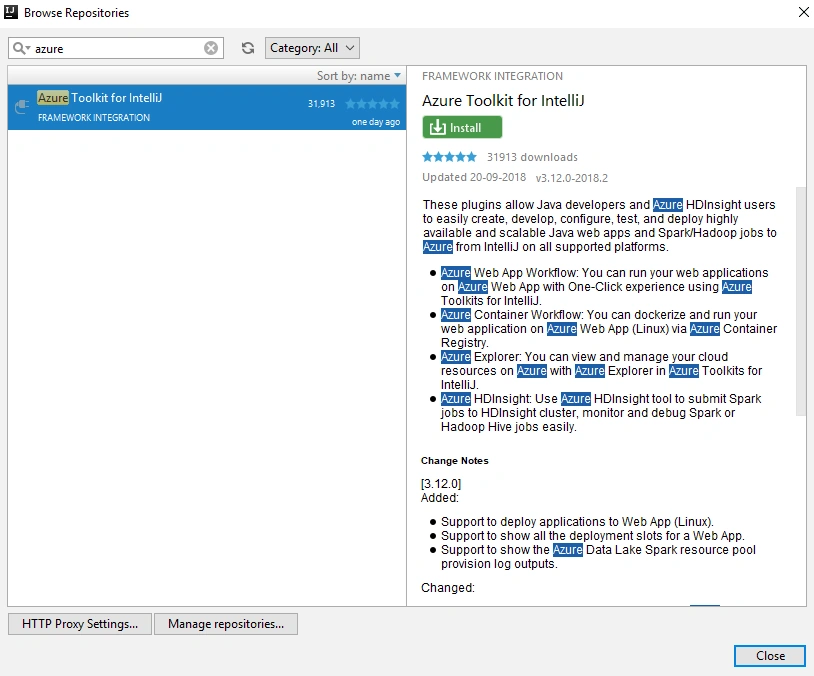 After successful plugin installation please re-run the IntelliJ.
Step 3 - Create a new Spark Scala Project
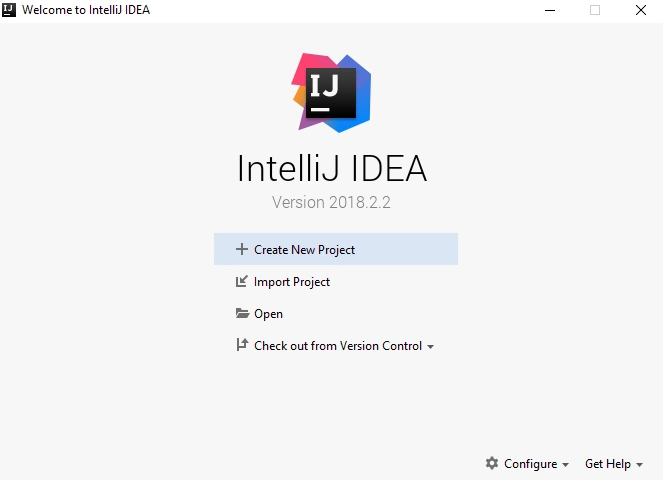
We can choose “Create New Project”
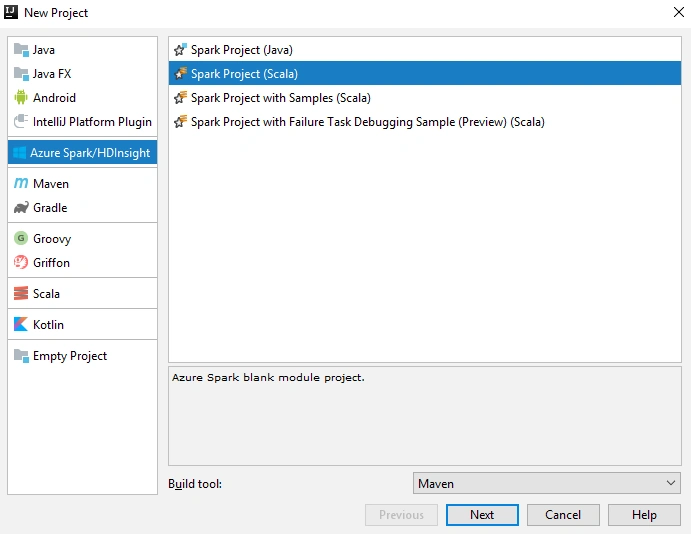
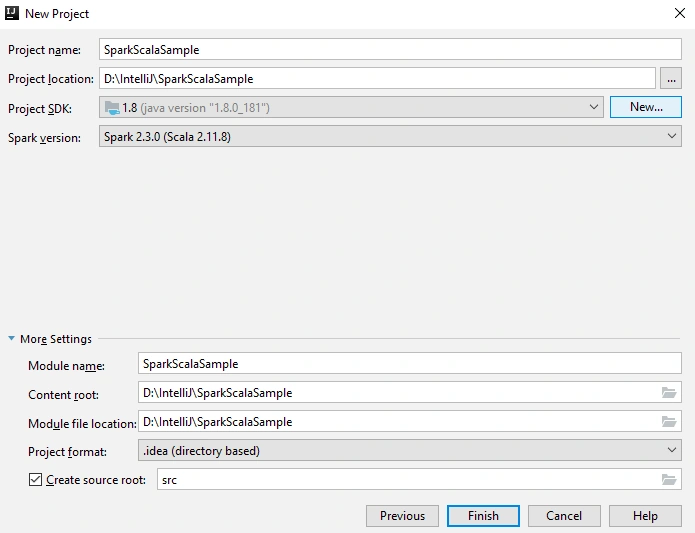
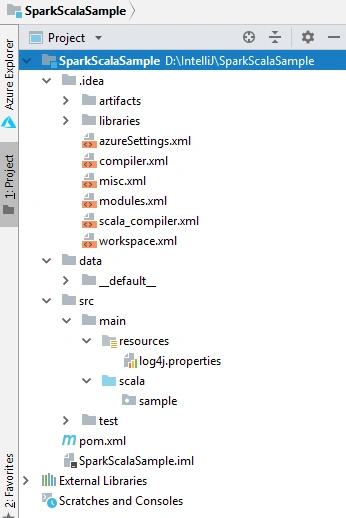
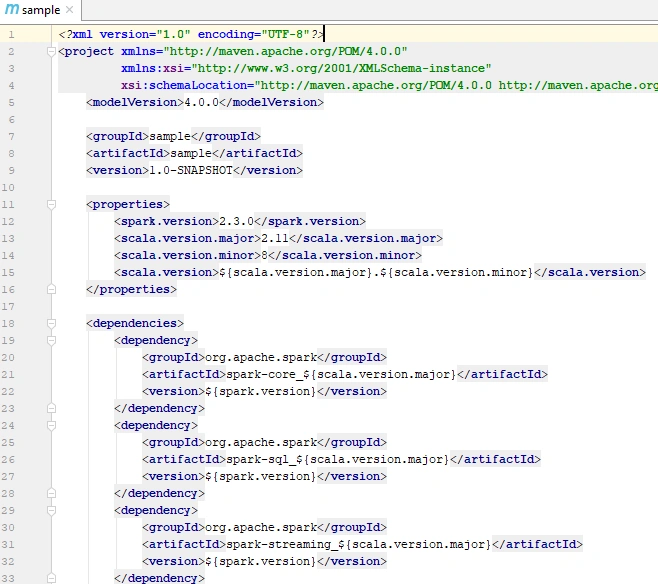
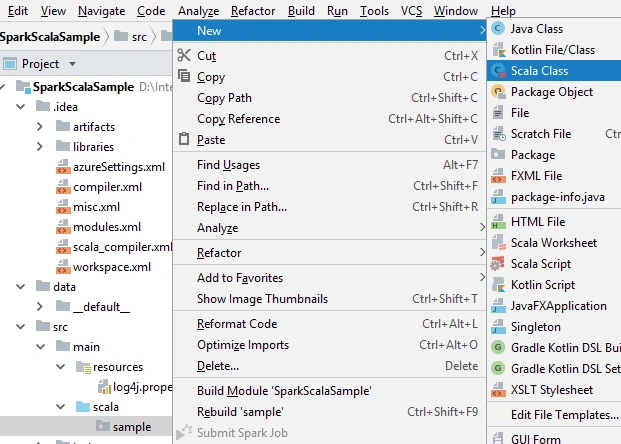
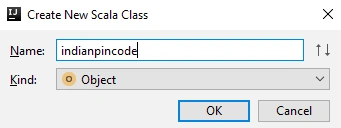
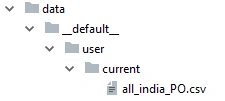
- package sample
- import org.apache.spark.sql.SparkSession
- object indianpincode {
- def main(arg: Array[String]): Unit = {
- val sparkSession: SparkSession = SparkSession.builder.master("local").appName("Scala Spark Example").getOrCreate()
- val csvPO = sparkSession.read.option("inferSchema", true).option("header", true).
- csv("all_india_PO.csv")
- csvPO.createOrReplaceTempView("tabPO")
- val count = sparkSession.sql("select * from tabPO").count()
- print(count)
- }
- }
In the next step, we have read the CSV file from our local mapped data folder and saved to a data frame variable “csvPO”
Next, we will create a temporary view from the above data frame variable.
We are using Spark SQL to query the data. Spark SQL is easy to use, and it looks like normal SQL queries.
We simply get the total record count of Pin code data and save it to a variable and we print that variable.
Step 4 - Run the Project
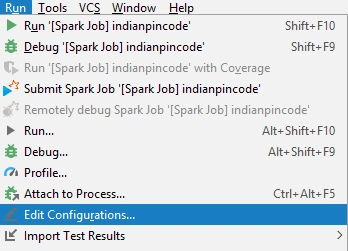
We can run our project now. Please click the Run menu and choose the “Edit Configurations” option.

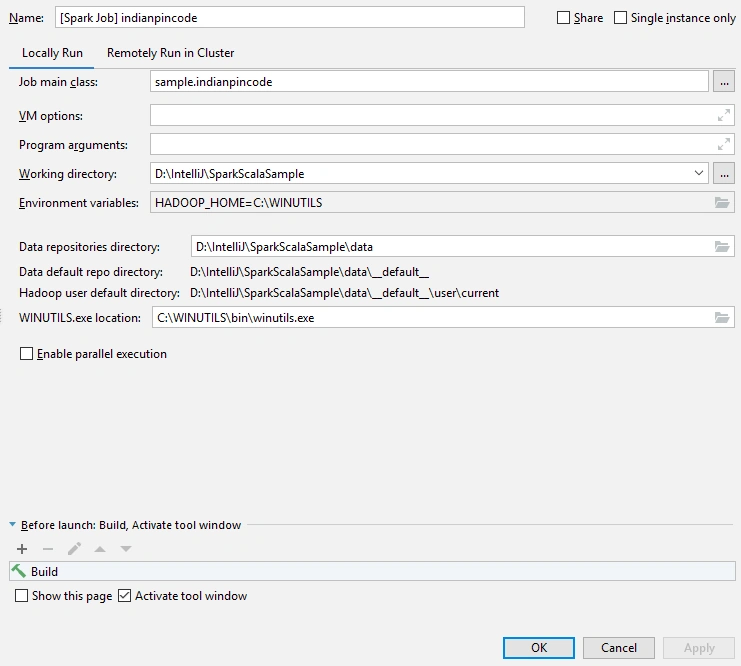
Give a name to our configuration and select the main class to run. In our case, this is an object file.
Please note running Spark application in the windows machine needs a winutils.exe utility.
Please download this utility from this link and copy it to your local directory. Please set an environment variable for this utility.
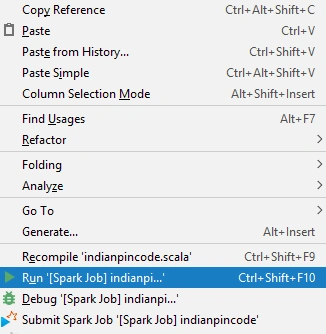
 Please right-click our object file “indianpincode.scala” and choose Run option. This will run our application locally.
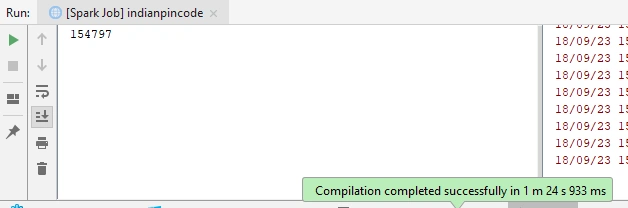
 It will take some moments to compile our application and we will get a result after some time. We have just taken the record count in this query.
 Now we can add one more line of code to get the state-by-state post office count. Run the application again in the same way and we will get the below result now.
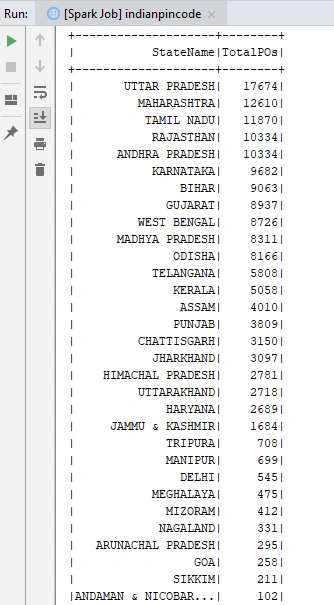
- sparkSession.sql("select statename as StateName,count(*) as TotalPOs from tabPO group by statename order by count(*) desc").show(50)
In this article, we saw how to install IntelliJ IDEA in our windows machine and we also installed Scala and Azure plugins in IntelliJ. Later we created a simple Spark Scala project and read the data from the local CSV file.
In the second part of this article, we will run the same application with the HDInsight spark cluster. I will explain all the steps to create an HDInsight spark cluster in the Azure portal.
wei zhaoPosted Dec 2, 2019, 5:57 PM
Very good introduction! I have a question, how to split the output from spark system message? What I get is that the output is mixed with spark system messages. Thank you!