
Introduction
The usage of large language models (LLMs) has revolutionized the way we approach complex tasks in AI, providing powerful tools for natural language understanding, generation, and more. Among the collection of LLMs available, Meta's Latest Llama 3.1 stands out as a robust model for various natural language processing (NLP) applications. Coupled with Microsoft's Semantic Kernel, developers now have a flexible framework to integrate these models into a wide range of applications, from chatbots to data analysis tools etc..
In this article, we'll explore the exciting capabilities of function calling using a local instance of Llama 3.1 hosted in ollama with Semantic Kernel. By leveraging this combination, developers can harness the full potential of Llama 3.1 while maintaining control over their data and computational resources with out using any cloud services. We’ll walk through the process of setting up a local LLM environment, integrating it with Semantic Kernel, and implementing function calling to perform specific tasks.
Why Use a Local LLM with C# Semantic Kernel?
Running LLMs locally brings several key advantages:
- Data Security: Your data remains within your local environment, ensuring privacy and compliance with data protection regulations.
- Customization: You can select various open source models that better suit specific use cases. SLM model like PHI3 for simple use case like summarization.
- Cost Savings: Avoiding the need for external APIs reduces ongoing costs.
- Low Latency: Local execution minimizes response times, improving performance for real-time applications.
The C# Semantic Kernel library provides a structured framework for integrating LLMs into your applications. It simplifies the process of calling functions, managing context, and orchestrating complex workflows, making it easier to deploy Llama 3.1 in real-world scenarios.
Setting Up Llama 3.1 Locally with Ollama
To begin function calling with a local instance of Llama 3.1 using C# Semantic Kernel, you'll need to follow a few setup steps.
First, you’ll need to set up the Llama 3.1 model from Ollama on your local machine. This involves:
- Hardware Preparation: Ensure your machine has the necessary computational power, preferably a GPU.
- Environment Configuration: Install the required software and dependencies. Follow the instructions provided by Ollama to download and run Llama 3.1 locally.
Step-by-Step Guide: Implementing Function Calling with Llama 3.1 Using C# Semantic Kernel
Step 1. Setup Your Project
-
Create a New C# Console Application:
- Open your preferred IDE (like Visual Studio or Visual Studio Code).
- Create a new Console Application project.
-
Install Required NuGet Packages:Install the following NuGet packages via the NuGet Package Manager or using the .NET CLI\
dotnet add package Microsoft.Extensions.Configuration dotnet add package Microsoft.SemanticKernel dotnet add package Microsoft.SemanticKernel.Connectors.OpenAI -
Configure User Secrets: Set up user secrets to securely store your model ID, base URL, and weather API key. This can be done via the .NET CLI:
Replacedotnet user-secrets init dotnet user-secrets set "modelId" "your-model-id" dotnet user-secrets set "baseUrl" "your-base-url" dotnet user-secrets set"weatherApiKey" "your-weather-api-key""your-model-id","your-base-url", and"your-weather-api-key"with your actual values. you can download free weather api key from weatherapi.com
Step 2. Configure the Application
- Load Configuration: Start by loading the configuration values from user secrets.
var config = new ConfigurationBuilder() .AddUserSecrets(Assembly.GetExecutingAssembly(), true) .Build(); var modelId = config["modelId"]; var baseUrl = config["baseUrl"]; var weatherApiKey = config["weatherApiKey"]; - Set Up the HTTP Client: Initialize an
HttpClientwith a timeout setting to manage the requests to your local Llama 3.1 model.var httpClient = new HttpClient { Timeout = TimeSpan.FromMinutes(2) }; -
Build the Semantic Kernel: Create and configure the Semantic Kernel using the
KernelBuildervar builder = Kernel.CreateBuilder() .AddOpenAIChatCompletion(modelId: modelId!, apiKey: null, endpoint: new Uri(baseUrl!), httpClient: httpClient); var kernel = builder.Build();
Step 3. Set Up the Chat Agent and Add Plugins
- Define Agent Instructions (Prompt) and Settings:
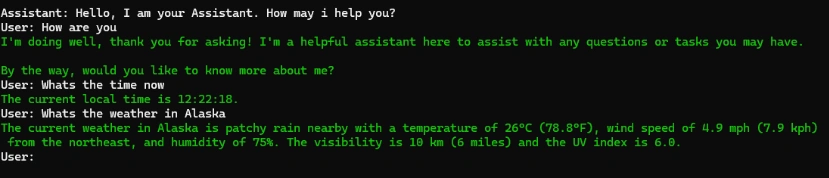
var HostName = "AI Assistant"; var HostInstructions = @"You are a helpful Assistant to answer their queries. Be respectful and precise in answering the queries. If the queries are related to getting the time or weather, Use the available plugin functions to get the answer."; var settings = new OpenAIPromptExecutionSettings() { Temperature = 0.0, ToolCallBehavior = ToolCallBehavior.AutoInvokeKernelFunctions }; ChatCompletionAgent agent = new() { Instructions = HostInstructions, Name = HostName, Kernel = kernel, Arguments = new(settings), }; - Add Plugins to the Agent: In this section, we will dive into the functionality of two key plugins used in our application: the
WeatherPluginand theLocalTimePlugin. These plugins are designed to handle specific tasks—retrieving weather details and getting the current local time—and they are integrated into the Semantic Kernel to be invoked when needed by the AI Assistant. - WeatherPlugin: The
WeatherPluginis a class that interfaces with a weather API to fetch and return weather details for a specified location. Here’s a breakdown of how it works:
Join the conversation! Your thoughts help the community grow.