
What is Colab?
Colab, or "Colaboratory", allows you to write and execute Python in your browser, with
- Zero configuration is required.
- Access to GPUs free of charge
- Easy sharing
Whether you're a student, a data scientist, or an AI researcher, Colab can make your work easier.
What is PySpark?
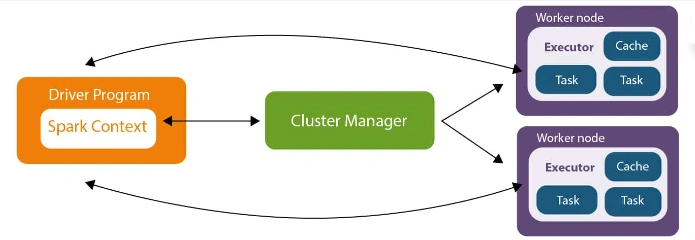
PySpark is a python-based API that is used for Spark. It is used for collaborating with Spark using APIs written in Python. It also supports Spark’s features like Spark DataFrame, Spark SQL, Spark Streaming, Spark MLlib, and Spark Core. It provides an interactive PySpark shell to analyze structured and semi-structured data in a distributed environment. PySpark supports reading data from multiple sources and different formats. It also facilitates the use of RDDs (Resilient Distributed Datasets). PySpark features are implemented in the py4j library in python.
Advantage
- Easy to use, learn and implement.
- Simple and Comprehensive API
- Support ANSI SQL
- Supports Spark, Yarn, and Mesos cluster managers.
- It features various options for data visualization, which is difficult using Scala or Java.
- Immutable.
- Dynamic in nature
- Error Handling
Disadvantage
- Sometimes, it becomes difficult to express problems using the MapReduce model.
- Since Spark was originally developed in Scala while using PySpark in Python programs they are relatively less efficient and approximately 10x times slower than the Scala programs. This would impact the performance of heavy data processing applications.
- The Spark Streaming API in PySpark is not mature when compared to Scala. It still requires improvements.
- PySpark cannot be used for modifying the internal function of the Spark due to the abstractions provided. In such cases, Scala is preferred.
Getting Started
In this article, I am going to use Google Colab.
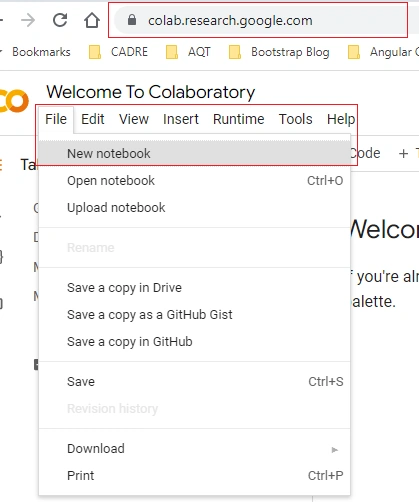
- Open the given URL https://colab.research.google.com/
- Sign in using your Gmail email address.
- Click the new notebook in the File tab to start a new notebook.
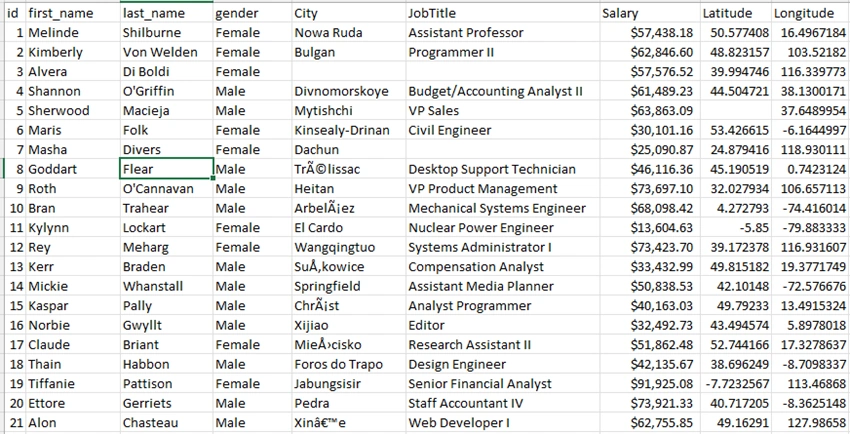
Here is my sample .csv data file screenshot to give an overview of how columns and data look like.
Easy way of Installing PySpark in Colab
The easiest way of installing PySpark on Google Colab is to use pip install.
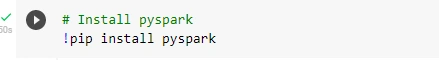
After installation, we can create a Spark session and check its information.
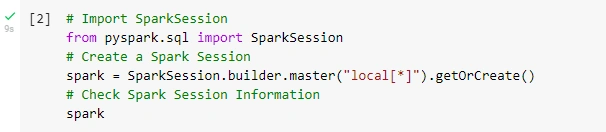
We can also test the installation by importing a Spark library.
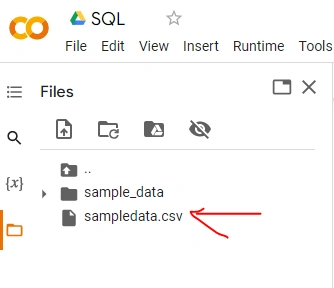
Now include the sample data file into the Colab notebook.
Now let’s load the CSV file data.
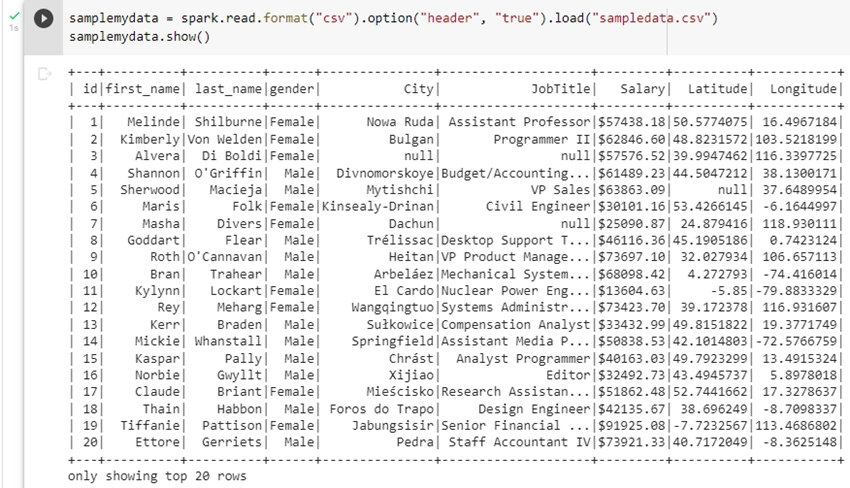
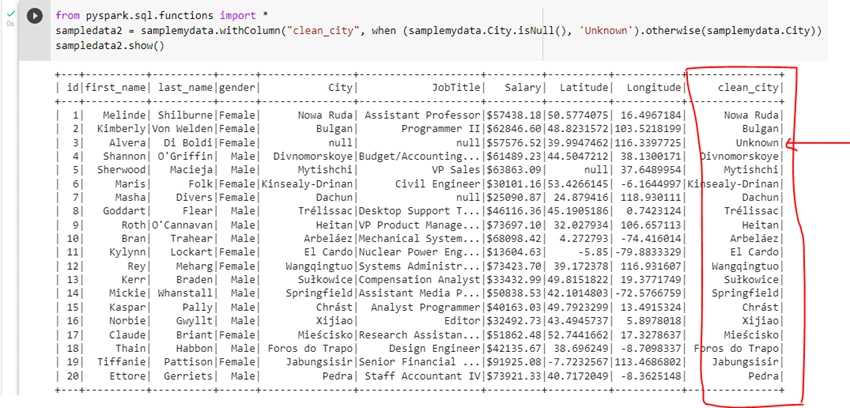
Let’s do some filtering and add some new columns with some logic.
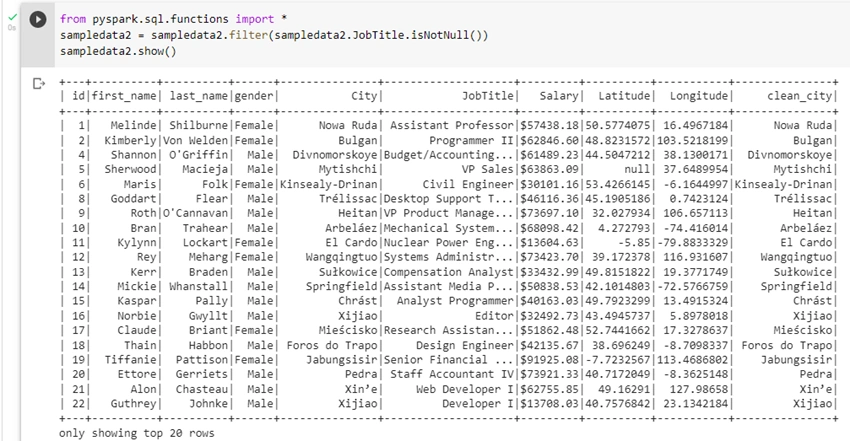
Filter data
PySpark Data Frame
PySpark DataFrames are data organized in tables that have rows and columns. Every column in its two-dimensional structure has values for a specific variable, and each row contains a single set of values from each column and names of columns cannot be ignored, Row names need to be unique, and the data that is stored can be character, numeric, or factor data types and there must be an equal number of data items in each column.
Let’s display data in the data Frame.
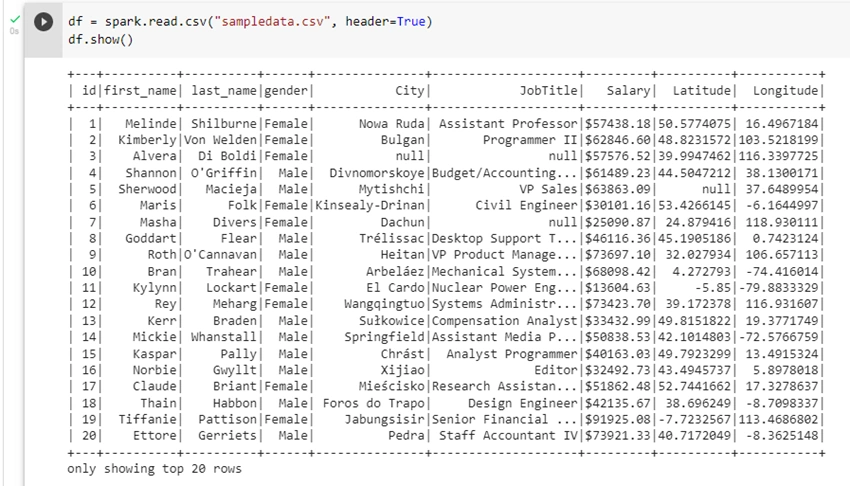
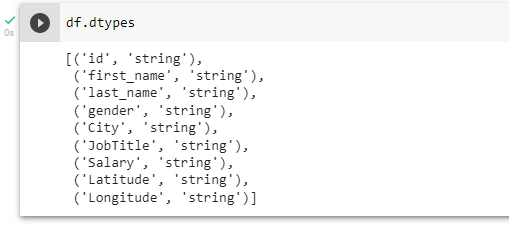
You can see column data types by using this command,
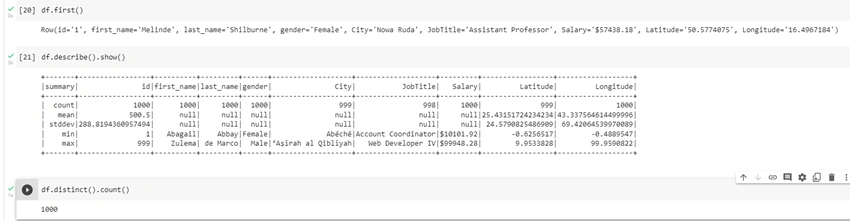
Some other useful commands like first, describe, and counts,
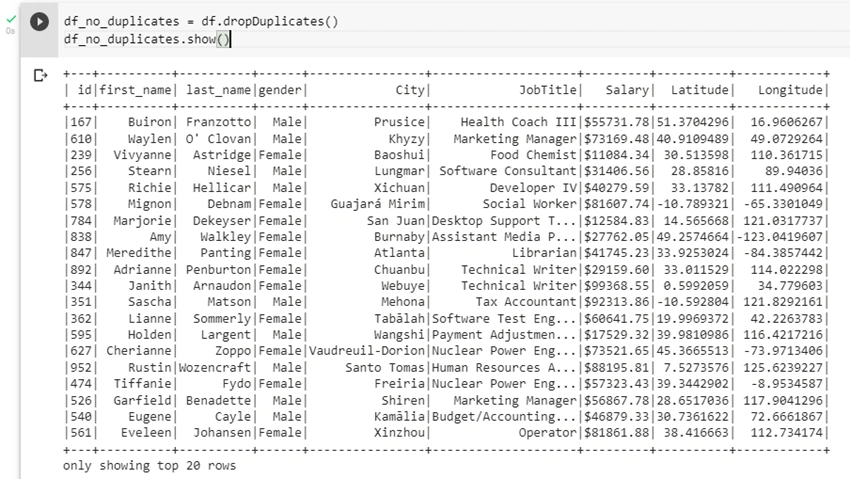
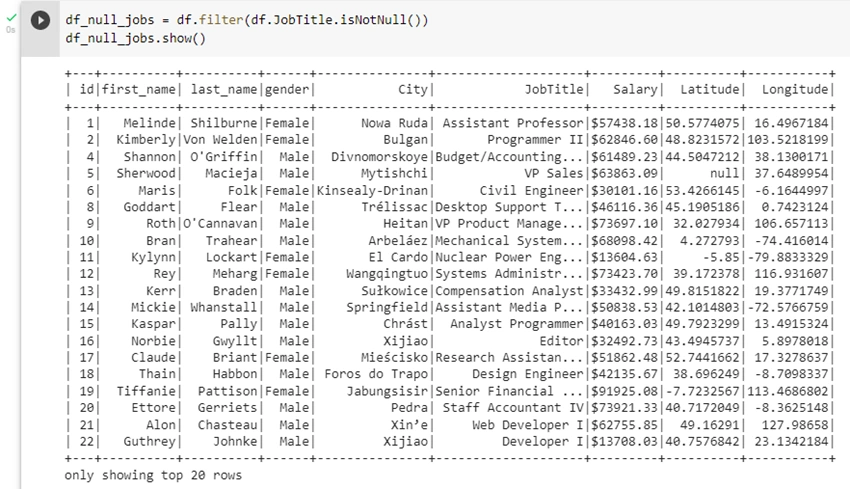
Handle duplicate and null values,
If there are any null values, then delete an entire row from the given data result,
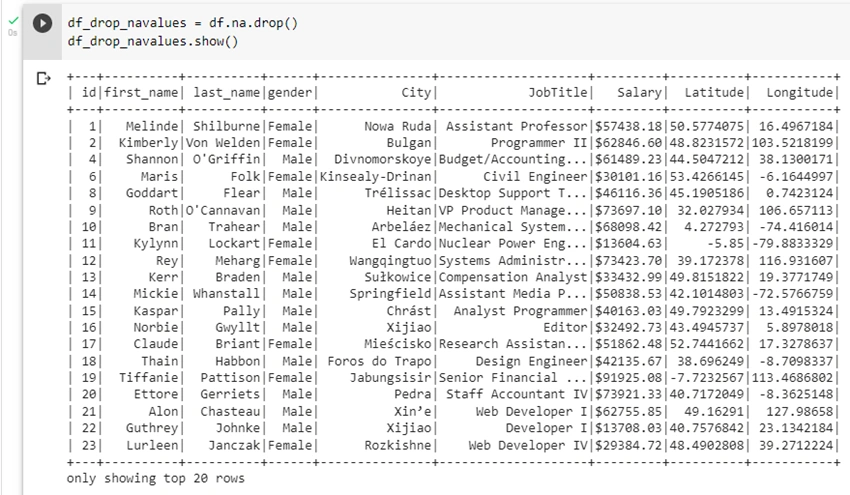
Another way
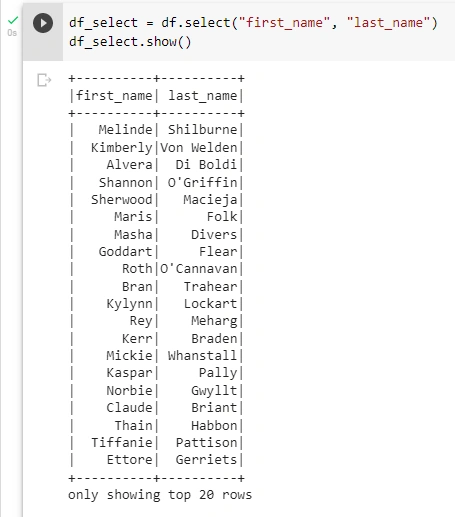
Let’s play some with select data,
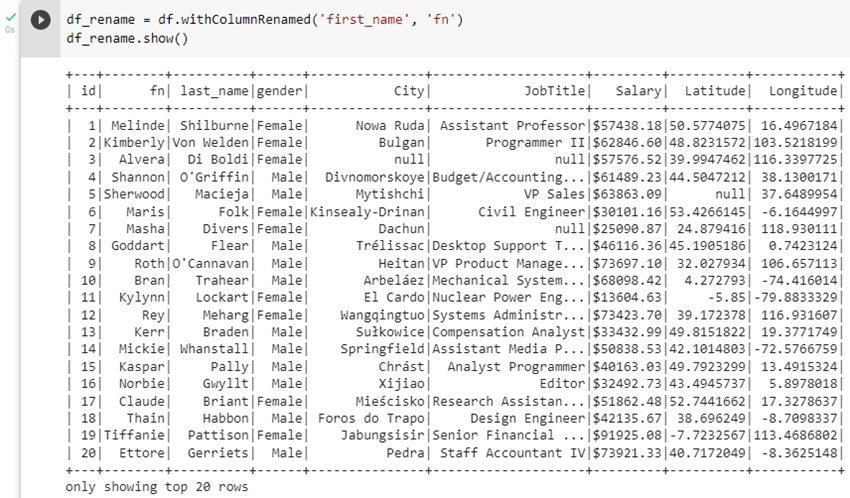
Rename column name,
Conclusion
In this article, we have learned how to setup Colab and install PySpark and run some data commands.
Join the conversation! Your thoughts help the community grow.