
Introduction
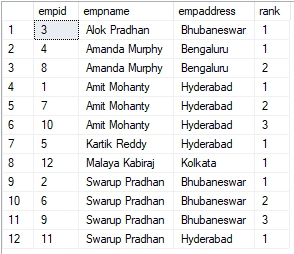
This article will teach us how to find and delete duplicate values from a SQL server table. Sometimes we may find duplicate values in a table, and we have to find the duplicate values from that table. In this article, we will find duplicate values using the "Group By and Having" clause, "Common Table Expressions (CTE)," and "Rank" function.
For this operation, we will create a table named “employee” and add some records.
CREATE TABLE [dbo].[employee](
       [empid] [int] IDENTITY(1,1) NOT NULL,
       [empname] [nvarchar](50) NULL,
       [empaddress] [nvarchar](50) NULL
) ON [PRIMARY]

INSERT INTO [dbo].[employee] VALUES('Amit Mohanty', 'Hyderabad')
INSERT INTO [dbo].[employee] VALUES('Swarup Pradhan', 'Bhubaneswar')
INSERT INTO [dbo].[employee] VALUES('Alok Pradhan', 'Bhubaneswar')
INSERT INTO [dbo].[employee] VALUES('Amanda Murphy', 'Bengaluru')
INSERT INTO [dbo].[employee] VALUES('Kartik Reddy', 'Hyderabad')
INSERT INTO [dbo].[employee] VALUES('Swarup Pradhan', 'Bhubaneswar')
INSERT INTO [dbo].[employee] VALUES('Amit Mohanty', 'Hyderabad')
INSERT INTO [dbo].[employee] VALUES('Amanda Murphy', 'Bengaluru')
INSERT INTO [dbo].[employee] VALUES('Swarup Pradhan', 'Bhubaneswar')
INSERT INTO [dbo].[employee] VALUES('Amit Mohanty', 'Hyderabad')
INSERT INTO [dbo].[employee] VALUES('Swarup Pradhan', 'Hyderabad')
INSERT INTO [dbo].[employee] VALUES('Malaya Kabiraj', 'Kolkata')
By Using Group By and Having a clause
By using Group By clause, we can group all table data as per our defined columns and count the duplicate occurrence of rows. We can use the COUNT function.
For example,
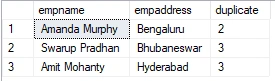
SELECT [empname], [empaddress], [duplicate] = COUNT(*)
FROM [dbo].[employee]
GROUP BY [empname], [empaddress]
HAVING COUNT(*) > 1;
In the above query, we will get all data having duplicated more than one, and the “[duplicate]” column shows how many duplicate records there are.
Now we need to keep one record and delete all duplicate records. We can use the “MIN” function to get the first record of all duplicate records.
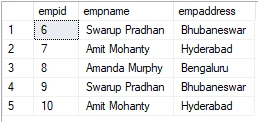
SELECT * FROM [dbo].[employee]
WHERE [empid] NOT IN (SELECT MIN([empid])
FROM [dbo].[Employee]
GROUP BY [empname], [empaddress]);
In the above query, we will exclude the minimum id of each duplicate row.
Metin EKENPosted Aug 9, 2022, 7:23 AM
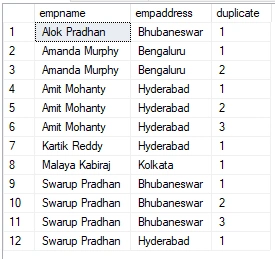
Hello, firstly thank you for working. I have a question about CTE. I want to listing only 2,3,4 duplicating rows. What am i add code?