
Problem Statement
Data Cleaning is an important part of ETL/ELT processes as it ensures that only high-quality data is loaded into the system. This helps to improve the accuracy of the data analytics.
So how to remove the duplicate records from the file as a part of the clean-up process via ADF / Synapse Pipeline.
Prerequisites
- Azure Data Factory / Synapse
Solution
In the case of SQL, for the below scenario assuming the Uniqueness of the rows is based on Column C1 values; the rows highlighted indicate the duplicate rows.
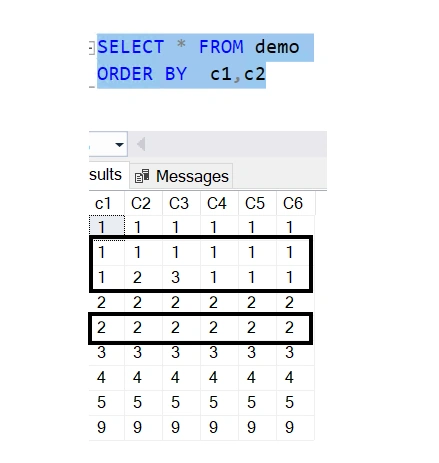
To remove the duplicate records in SQL, we can make use of the ROW_NUMBER and PARTITION / OVER BY function as seen below
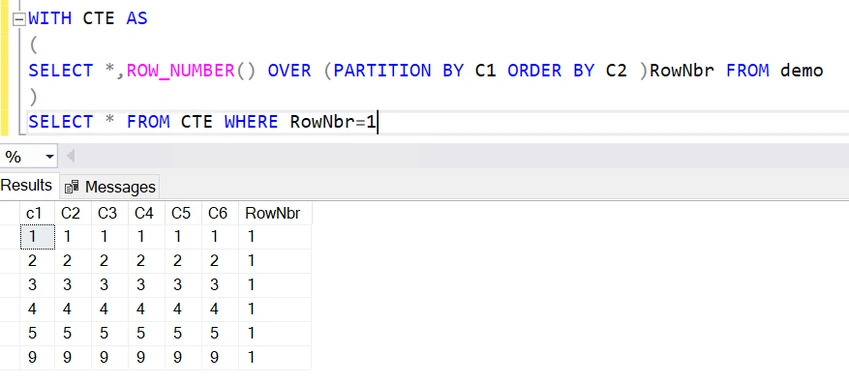
To Cleanse the file of duplicate records via Azure Data Factory / Synapse, we can leverage the similar concept of ROW_NUMBER and PARTITION / OVER BY.
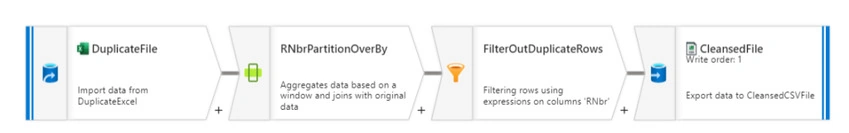
We would leverage Dataflow activity to achieve the use case.
Below is the flow for the same.
Sample File
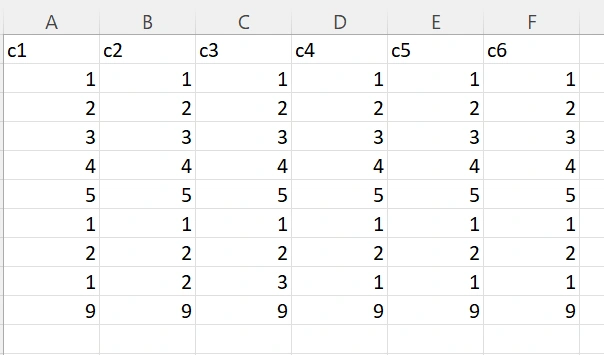
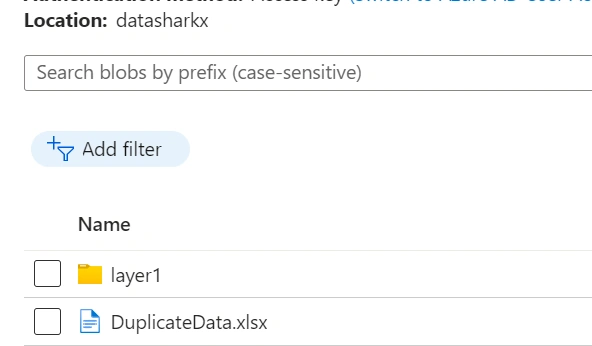
Create a Source flow and the corresponding dataset mapping to the Azure Blob storage (in this scenario) location wherein the duplicate data file is present.
Source location
Dataset
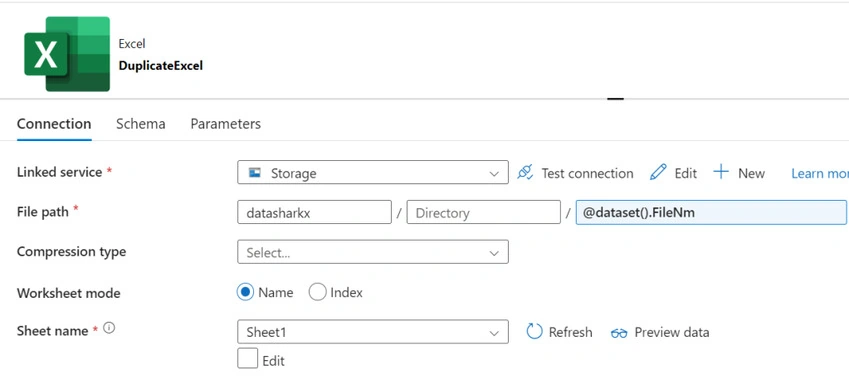
where Dataset Parameter
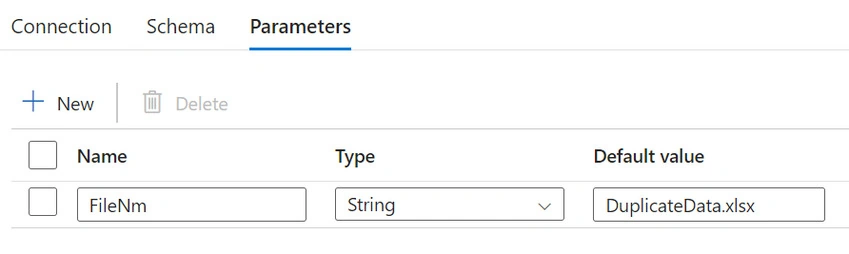
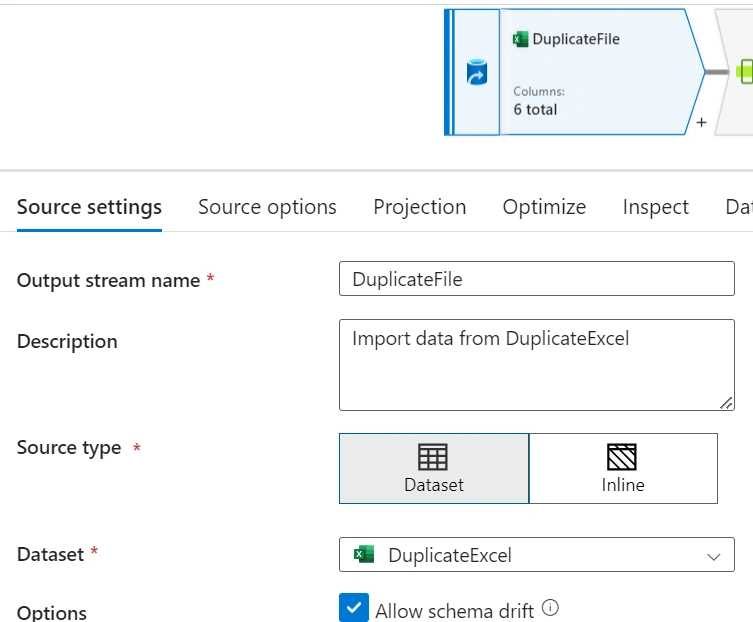
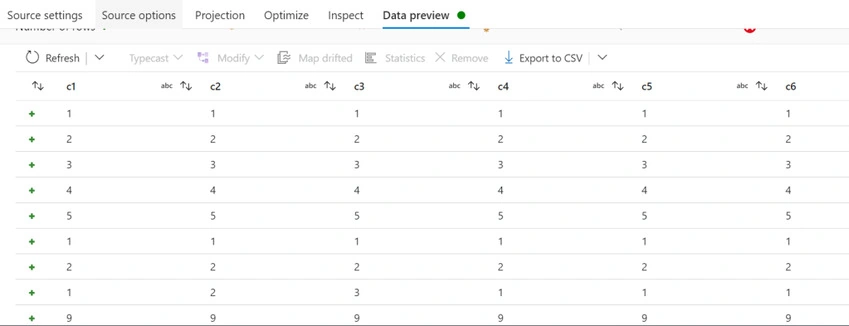
Data Preview
- Select the Window function to derive the ROW_NUMBER functionality.
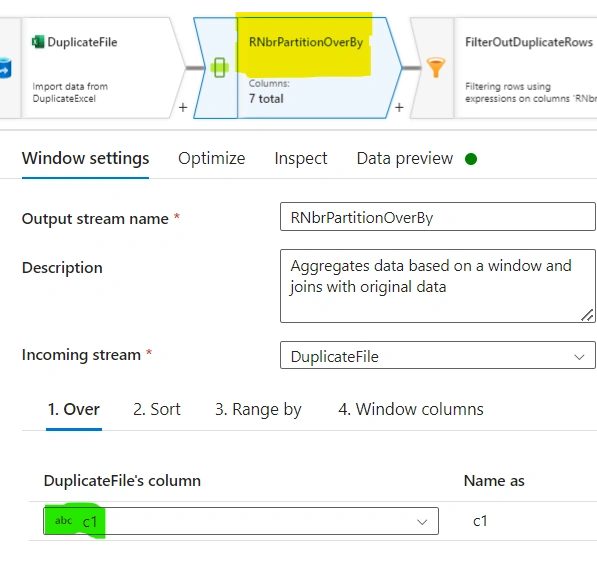
- Select the column via which we need to Partition.
Note. In the case of Composite keys, we can select multiple columns.
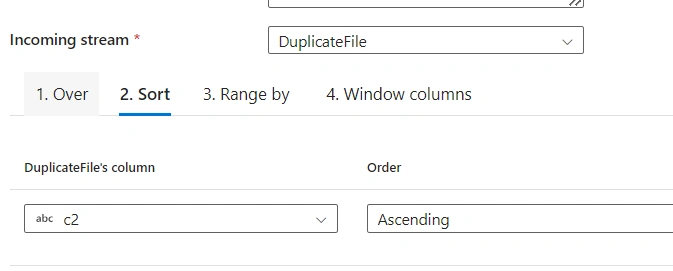
- In Sort, select the column via which we need to sort in case of duplicate rows.
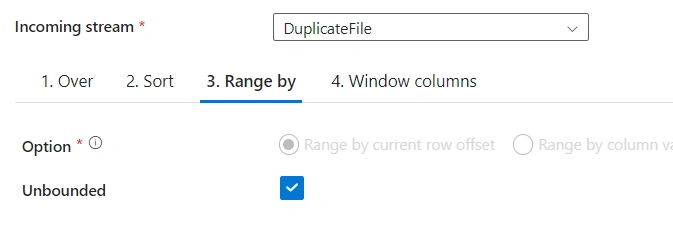
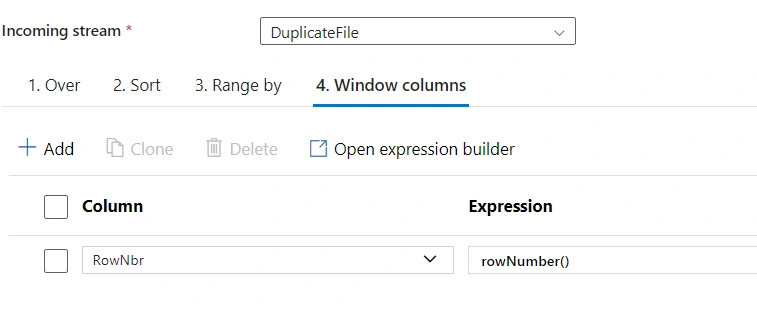
- Add a Column with the name, RowNbr, with the expression as rowNumber().
Data Preview
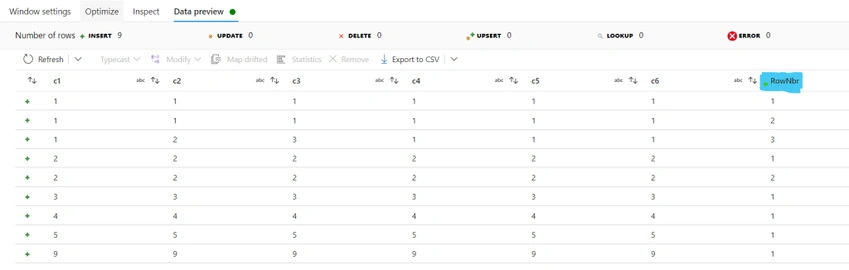
Filter the records with RowNbr equal to one as those represent unique rows via the Filter function.
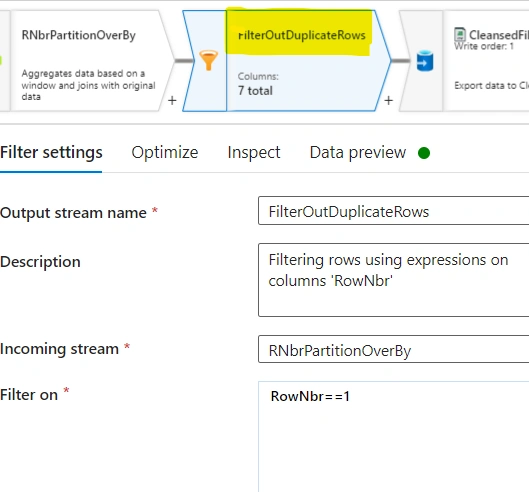
//Filter On Expression :
RowNbr==1
Data Preview
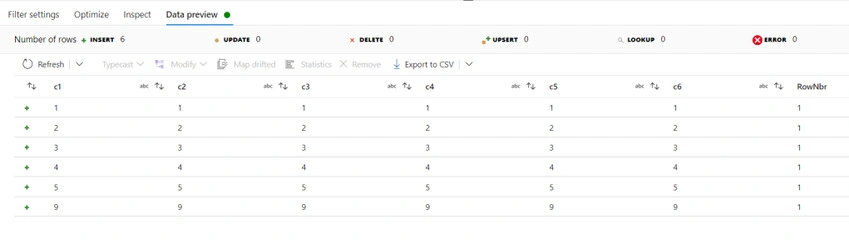
Finally, add a Sink section to generate the cleansed file.
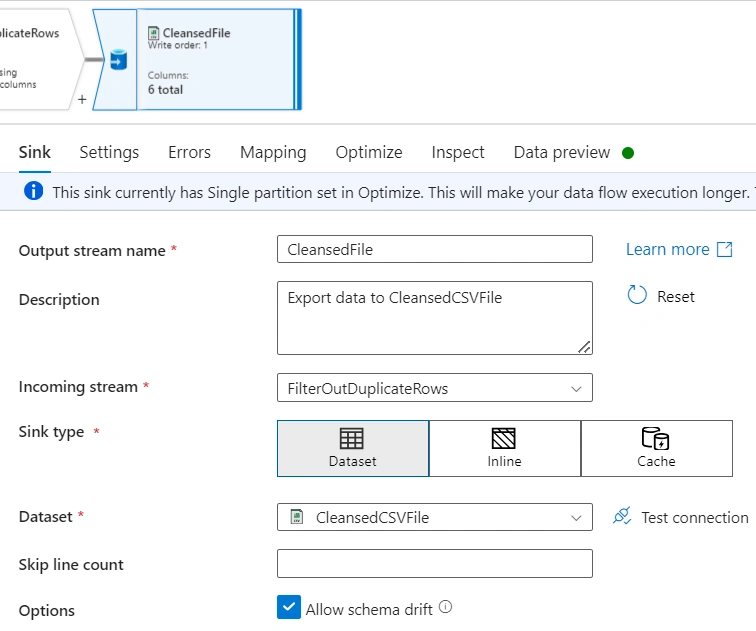
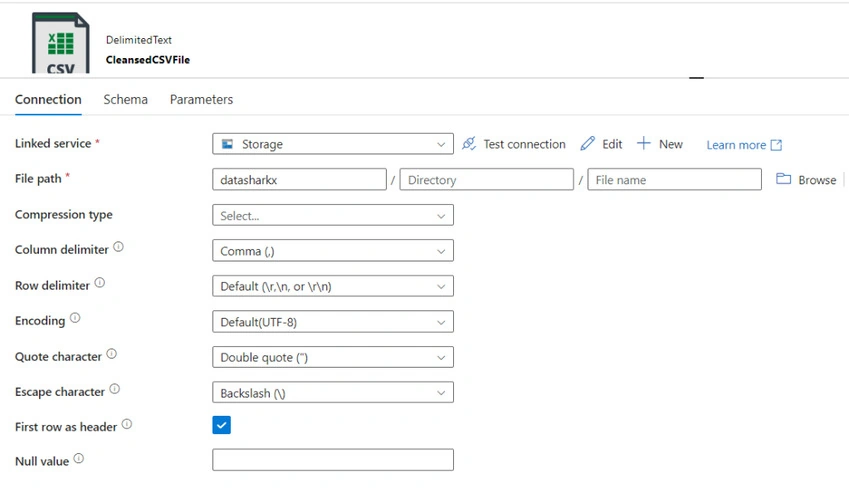
where Dataset
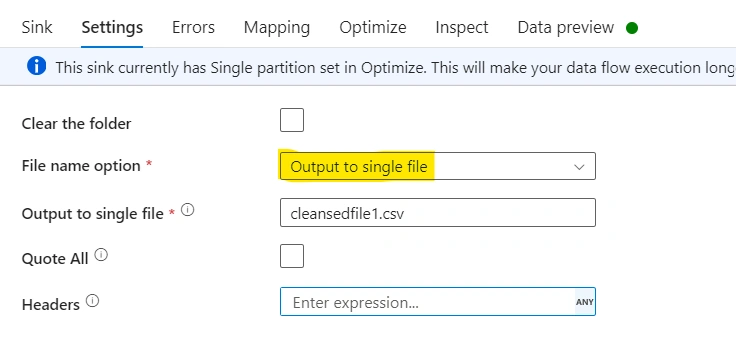
With Sink Settings as below
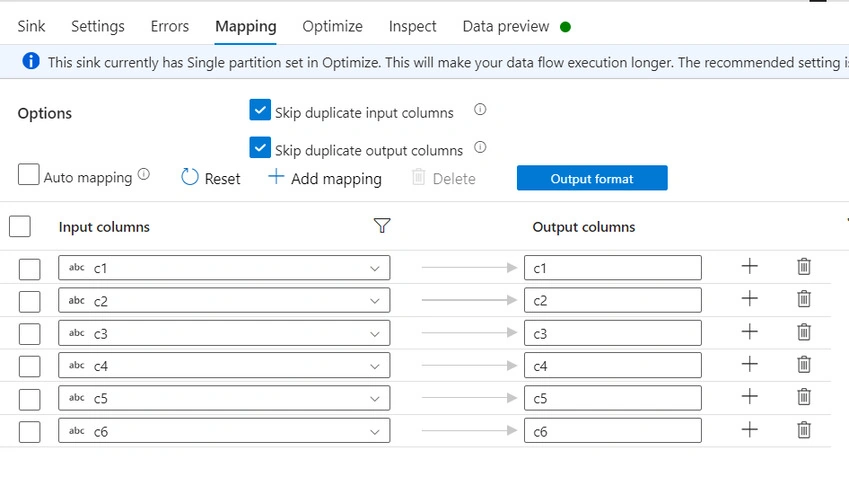
And in Mapping, delete the additional column RowNbr mapping.
Output
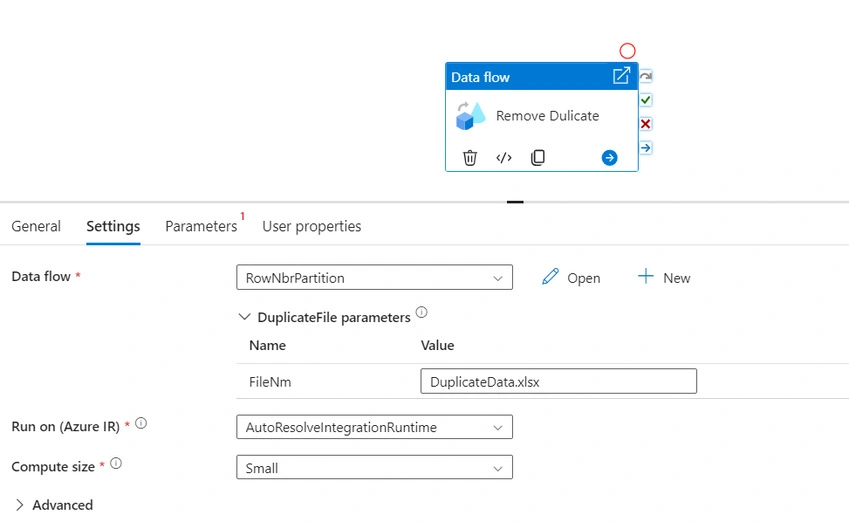
Create a Pipeline, call the Dataflow via Dataflow activity, and trigger the pipeline.
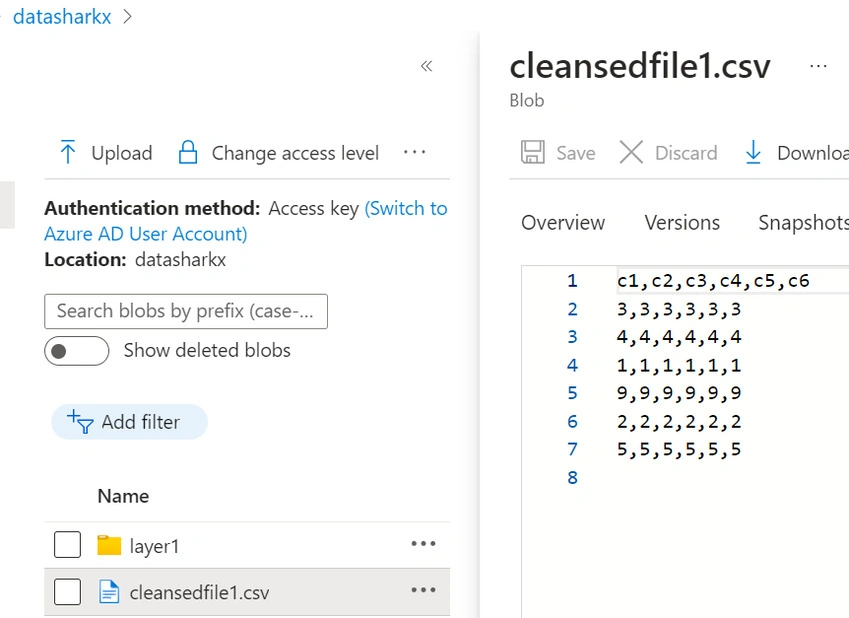
Result
Join the conversation! Your thoughts help the community grow.